AI Chips & Infrastructure
Beyond GPUs and External HBM: How Cerebras Is Challenging AI Computing With the World’s Largest Chip
Cerebras built an entire processor from a silicon wafer, betting that massive on-chip memory and communication can reduce the data-movement bottlenecks of conventional GPU clusters.
Most AI chip companies are advancing along the same path: build more powerful GPUs, add more high-bandwidth memory and connect thousands of accelerators through increasingly fast networks.
Cerebras Systems chose a different route.
Instead of slicing a silicon wafer into hundreds of individual chips, the U.S. company turns nearly the entire wafer into one enormous processor. Its Wafer Scale Engine, or WSE, combines a vast number of compute cores, on-chip memory and a communication fabric in one device—seeking to perform work that would otherwise be distributed across many GPUs.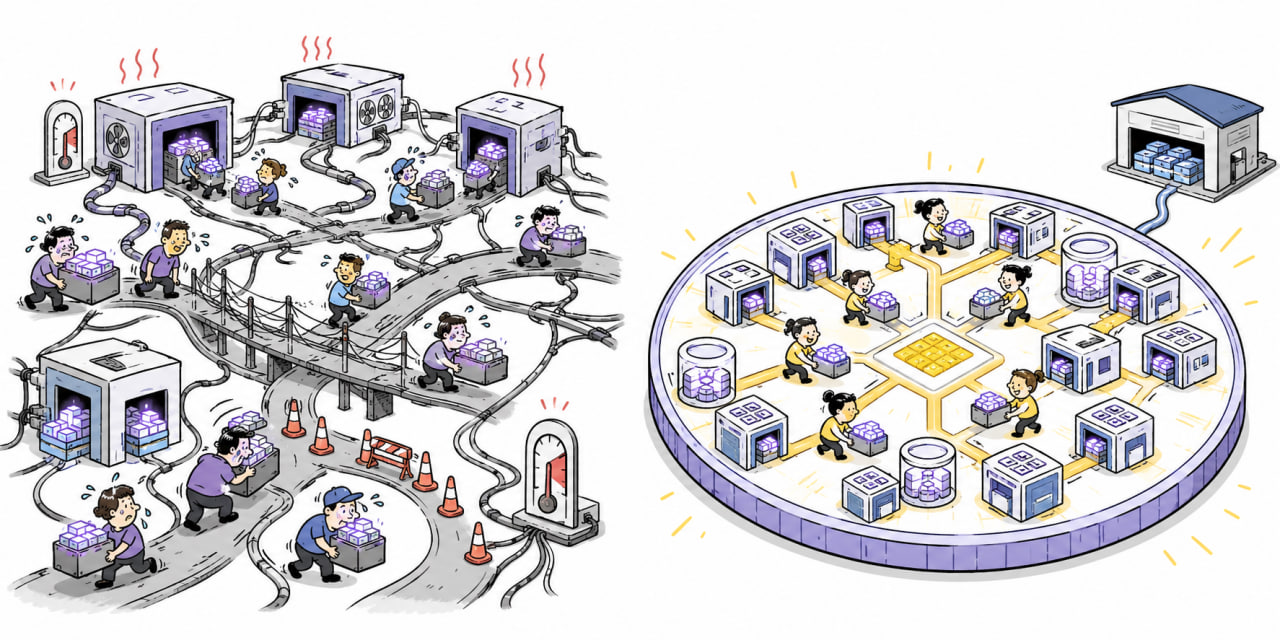
It is an unusually aggressive architectural experiment—and part of a larger story spanning early speech recognition, deep-learning scaling laws and the modern race for AI infrastructure.
Why Turn an Entire Wafer Into One Processor?
Conventional semiconductor manufacturing produces many chips on one silicon wafer, cuts the wafer apart and packages the working dies individually.
There is a practical reason for that approach: the larger a chip becomes, the more likely it is to contain a manufacturing defect. If one wafer contains only a single processor, even a localized defect could threaten the entire product, making yield and cost difficult to control.
Cerebras attacks that problem with redundant cores, an on-chip network that can route around defects and specialized packaging. The goal is to keep the system operational even when portions of the wafer are imperfect.
The primary attraction of wafer-scale computing is shorter data movement.
In a GPU cluster, model data repeatedly moves among compute cores, HBM, other GPUs and other servers. As models expand, performance is often limited not only by the amount of arithmetic available, but by whether data can reach each computing unit quickly enough.
The WSE places large amounts of compute, memory and interconnect on one enormous piece of silicon. For highly parallel and communication-intensive AI workloads, this approach may be simpler than coordinating large numbers of separate accelerators.
Does Cerebras Really “Bypass HBM”?
That phrase requires careful interpretation.
Modern GPUs rely on HBM because large models must access enormous numbers of parameters and intermediate values at high speed. HBM is expensive and capacity-constrained, while moving data between memory and GPUs also consumes substantial energy.
Cerebras integrates a large amount of SRAM directly onto the wafer. SRAM sits closer to the compute cores and offers lower latency and very high bandwidth, but it is costly in silicon area and cannot expand without limit. Very large models still require system-level memory and storage; the difference lies in how data is organized and delivered.
The Real Architectural Question
If more compute and memory can live on one wafer, can an AI system reduce data movement enough to deliver better training or inference efficiency?
Cerebras is not challenging the idea that memory is necessary. It is challenging the standard architecture in which compute chips, external HBM and high-speed networking are distributed across many devices.
A Company Shaped by the Early Speech-Recognition Era
Cerebras’ technical story is closely connected to the early scaling of deep-learning speech recognition.
Co-founder and CEO Andrew Feldman previously founded SeaMicro, a low-power server company later acquired by AMD. That experience gave him a background in chip startups, server systems and capital-intensive hardware businesses.
The Cerebras team also attracted researchers with deep-learning and high-performance-computing experience, including Greg Diamos.
Diamos worked on CUDA and GPU computing at Nvidia before joining Baidu’s Silicon Valley AI Lab, where he studied how to scale deep-learning training. His work included the end-to-end speech-recognition system Deep Speech and research into the relationship among model performance, compute and data scale.
Researchers were developing an important intuition: model capability was shaped not only by architecture, but could improve in relatively predictable ways as compute, data and parameter counts increased.
That broader pattern would later be described more systematically as scaling laws.
Baidu’s Silicon Valley Lab and the Early Search for Scaling
In the mid-2010s, Baidu established an AI research team in Silicon Valley to use large-scale computing for speech recognition and deep learning.
Deep Speech became one of its most visible projects. Researchers used end-to-end neural networks to convert audio directly into text, reducing the number of hand-engineered components common in traditional speech systems.
Training the system required extensive labeled audio, computing power and distributed engineering. The team explored not only whether the model worked, but how accuracy changed when data, model size and compute continued to grow.
Those experiments were not the sole origin of the later scaling-law literature for large language models. They did, however, reinforce a central industry lesson: when architecture and training methods remain relatively stable, more model capacity, more data and more computation can often deliver measurable improvements.
Dario Amodei also worked at Baidu’s Silicon Valley AI Lab before joining OpenAI and later co-founding Anthropic. His subsequent work contributed to large-scale model training, safety research and the development of scaling-law thinking.
Important distinction: Scaling laws should not be credited to one individual or one laboratory. They emerged from accumulating work across speech, vision, language modeling and distributed computing.
Why Scaling Laws Accelerated the AI Chip Race
Scaling laws created a powerful expectation: if model performance continues improving with compute, data and parameter scale, then larger training runs may produce more capable general-purpose systems.
That expectation encouraged technology companies and AI labs to buy more GPUs, construct larger data centers and invest in high-speed networking, HBM and electricity infrastructure.
Expansion also exposed the bottlenecks of conventional clusters:
- ◆GPUs must exchange enormous volumes of data;
- ◆HBM capacity and bandwidth constrain how models operate;
- ◆Communication across servers adds latency and energy use;
- ◆Programming, scheduling and recovering large clusters is complex;
- ◆Power and cooling costs grow rapidly with system size.
Cerebras’ wafer-scale architecture emerged in response to these constraints. It does not reject scaling laws; it aims to provide a computing platform better suited to continuing the scaling process.
The Advantages—and Costs—of One Enormous Chip
Wafer-scale computing offers exceptionally high on-chip bandwidth and shorter communication distances. Developers may be able to avoid dividing every workload across thousands of separate GPUs and reduce some complex distributed-communication code.
The architecture also faces substantial challenges:
| Manufacturing | Wafer-scale fabrication and packaging must solve power delivery, cooling, defect tolerance and mechanical stability. |
| Software migration | Customers already have major investments in CUDA and GPU clusters. New hardware needs mature tools, model compatibility and production operations. |
| Versatility | GPUs support training, inference, scientific computing, graphics and extensive industry software. A specialized system must justify switching costs. |
| Market change | Smaller models, quantization, sparsity, specialized chips and cloud services may change demand for very large systems. |
Cerebras cannot be evaluated by chip size alone. Performance per dollar, performance per watt, deployment speed, software usability and actual customer utilization matter more.
Cerebras Is Challenging More Than Nvidia
At first glance, Cerebras is competing with GPUs. More fundamentally, it is challenging the dominant AI infrastructure architecture: discrete accelerators, external HBM, high-speed switches and large server clusters.
Nvidia’s advantage comes not only from GPU performance, but from CUDA, a vast developer base, networking products and an integrated data-center platform. To become a durable alternative, wafer-scale computing must prove that it is not only fast in selected demonstrations, but also less expensive, reliable and easier to operate in real production environments.
Google’s TPUs, Amazon’s Trainium, custom accelerators from Microsoft and Meta, and a range of AI chip startups are all searching for routes beyond standard GPU deployments. Cerebras is simply one of the most aggressive—and visually dramatic—approaches.
What Really Matters About the “World’s Largest Chip”
The most important thing about Cerebras is not that its chip is enormous.
It asks a fundamental question: as models and token demand grow, will connecting ever more discrete GPUs always be the most efficient way to scale?
Wafer-scale computing offers a different answer—shorten data movement and concentrate compute, memory and communication in one physical system. Even if the architecture never replaces GPUs broadly, it may force the industry to reconsider where the boundaries of an AI chip should be drawn.
Cerebras is not merely building a faster conventional chip. It is attempting to redefine how large a “chip” can be—and how an AI computing system should be organized.